How Machine Learning Works in Real Systems
How machine learning works becomes much easier to grasp when you break it down into a few core steps. At the simplest level, machine learning helps computers find patterns in data and use those patterns to make predictions or decisions. It may sound complex at first, but the basic idea is fairly direct.
Instead of hard-coding every rule, people give the system examples. It studies those examples, adjusts its internal parameters, and then tries to deal with new data on its own. That is the core of it.
The basic idea behind machine learning
Traditional software follows rules written by a developer. If you want a program to sort email, detect fraud, or recommend a song, someone usually has to define the logic. Machine learning works differently. It learns patterns from data instead of depending only on fixed instructions.
That does not mean the system understands information the way a person does. It means it can spot relationships that would be difficult to describe manually. A model might learn that certain word combinations often show up in spam, or that specific customer behavior is linked to a higher chance of leaving a service.
That is what makes machine learning useful in situations where the rules are messy, constantly changing, or simply too numerous to write by hand.
Data is the starting point
Everything starts with data. Without it, there is nothing to learn from. And in machine learning basics, one point comes up again and again: quality matters just as much as quantity.
Data can come from many sources, including text, images, numbers, sensor readings, click activity, transaction records, and software logs. What matters most is whether that data actually reflects the problem you are trying to solve.
In many cases, the data includes examples with known outcomes. That helps the system learn the connection between an input and a result. If you are building a spam filter, for example, the model may be trained on emails already labeled as spam or not spam. It studies those examples and starts looking for useful patterns.
If the data is incomplete, messy, or biased, the model can learn the wrong thing. That is one of the most important parts of machine learning explained plainly: a model can only learn from the signals it is given.
Training turns examples into a model
Training is the stage where learning actually happens. During training, the algorithm works through many examples and adjusts itself to reduce errors. Over time, it gets better at connecting inputs with outputs.
A simple way to picture training machine learning models is to think of a student doing practice problems. The first attempts may be weak. After seeing more examples and correcting mistakes, the student improves. A machine learning system follows a similar pattern.
The result is a model. That model is the learned structure that can later be applied to new data. It is not just a stored file, even if it may be saved that way. It is the outcome of the learning process itself.
Different approaches handle training in different ways. Some learn from labeled examples, some look for hidden structure in unlabeled data, and some improve through repeated feedback. The underlying idea stays the same: the system changes based on experience.
Supervised learning and other common approaches
One of the most common approaches is supervised learning. In supervised learning, the model is trained on data where the correct answer is already known. This is useful when the goal is to predict a category or estimate a value.
A supervised model might learn to classify an email as spam or not spam, estimate house prices, or predict whether a customer is likely to cancel a subscription. Because the right answers are available during training, the model can compare its output with the expected result and adjust.
Another common approach is unsupervised learning. Here, the data does not come with labels. The system tries to find structure on its own, such as groups of similar items or unusual patterns. That can be useful for customer segmentation, anomaly detection, or exploring large data sets.
There is also reinforcement learning, where a system learns by taking actions and receiving feedback. Over time, it repeats what works and avoids what does not. This approach is often tied to control tasks and decision-making problems.
The methods differ, but the principle is the same. Patterns in data can guide future decisions.
How a model makes predictions
After training, the model is tested on data it has not seen before. This part matters because a useful model should do more than remember examples. It has to deal with unfamiliar cases too.
When new input arrives, the model processes it using the patterns it learned during training. It then produces an output, such as a label, a score, or a prediction. It might decide that a message is likely spam, or estimate the probability that a customer will make a purchase.
The result will not always be perfect. Machine learning is built around probability and approximation, not certainty. Even a strong model will sometimes get things wrong.
What makes it valuable is that it can perform well enough to support work at scale, reduce manual effort, or highlight patterns that would be hard to catch otherwise. That is one reason so many machine learning use cases show up in production systems.
Why feature quality matters
A model usually does not work with raw data in the same way a person would. It often relies on features, which are measurable parts of the data that help it learn.
In practice, a feature is a useful signal. For a retail model, that might include purchase history, browsing behavior, or time since the last order. For a text model, features may come from word patterns or other language signals. For an image model, they may reflect shapes, edges, or more abstract visual patterns.
The choice and preparation of features can make a huge difference. If the signals are weak or irrelevant, the model may struggle. If they are meaningful, learning tends to be much more effective.
This is why machine learning is not only about algorithms. It also depends on careful data preparation and a clear understanding of the problem.
Models can overfit or underfit
A model can learn too little, and it can also learn too much. Neither is good.
If the model is too simple, it may miss important patterns in the data. That is called underfitting. In that case, performance is weak because the model has not learned enough.
If the model becomes too closely tuned to the training data, it may memorize details that do not hold up on new inputs. That is overfitting. It can look great during training and still fail when it faces real-world data.
The goal is balance. A good model should capture useful patterns without locking onto noise or accidental details. This is why testing on separate data matters so much. It gives a more honest picture of how the model is likely to behave in practice.
Evaluation shows whether the model is useful
Once a model has been trained, it needs to be evaluated. That means checking how well it performs on data that was not used during training.
The way you evaluate it depends on the task. For classification, people may look at how often the model assigns the right label. For prediction tasks, they may measure how close the output is to the real value. Often, one metric is not enough, because a single number rarely tells the whole story.
Technical performance is only part of the picture. A model can score well in testing and still be a poor fit if it is too slow, too fragile, or too difficult to maintain. In real systems, practical value matters as much as accuracy.
Why machine learning is used so widely
Machine learning is widely used because it can handle tasks that are repetitive, data-heavy, or hard to define with fixed rules. It becomes especially useful when patterns are buried inside large amounts of information.
Common machine learning use cases include spam filtering, recommendation systems, fraud detection, image recognition, speech processing, demand forecasting, and customer support automation. In each case, the model helps process information faster or more consistently than a fully manual approach.
It is also useful when conditions change over time. A model can be retrained on newer data so it stays relevant. That ability to adapt is a big reason machine learning has become part of so many digital products and systems.
The limits are just as important as the benefits
Machine learning is powerful, but it is not magic. It will not solve every problem, and it should not be applied without thinking through the risks.
One issue is bias in the data. If the examples are skewed or incomplete, the model may reproduce those same problems. Another issue is explainability. Some models are easier to understand than others, and in sensitive contexts that can matter a lot.
Conditions can change too. A model trained on older patterns may become less accurate when the real world shifts. That is why monitoring and retraining are part of responsible practice.
In other words, a model is not a final answer. It is a tool, and like any tool, it has to be checked, maintained, and used with judgment.
What beginners should focus on first
If you want machine learning explained simply, start with the link between data, patterns, and predictions.
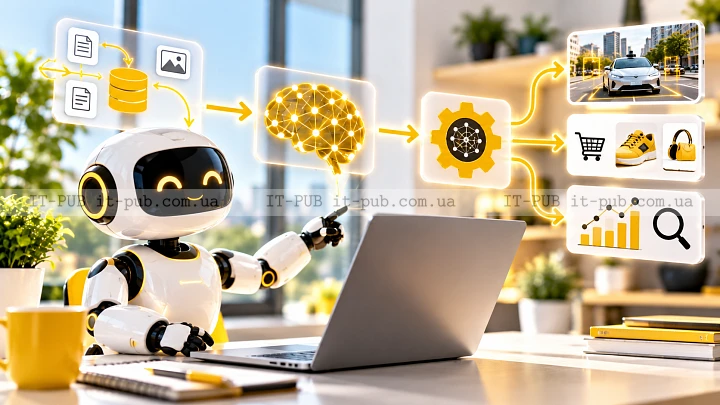
The flow is straightforward. Data provides examples. The algorithm studies those examples. Training turns them into a model. The model then makes predictions on new inputs. If those predictions are useful, the system has learned something valuable.
That loop sits at the center of machine learning basics. Once it clicks, the more advanced topics become easier to place. Supervised learning, feature engineering, evaluation, and tuning are all parts of the same larger process.
Machine learning in real projects
In real projects, machine learning is usually just one part of a larger system. It may sit inside an app, a website, a business workflow, or a data platform. The model itself is only one component. Data collection, cleaning, deployment, monitoring, and maintenance matter just as much.
That is why work in this area involves both technical and practical decisions. A team has to decide what problem is worth solving, what data is available, how the model will be used, and how success should be measured. A technically impressive model is not enough if it does not solve a real need.
That mindset is useful whether you are new to the field or already working in IT. It keeps attention on outcomes, not just algorithms.
Why the idea still matters
Machine learning continues to shape digital products because it lets systems adapt to patterns instead of relying only on fixed rules. That makes software more flexible and often more useful.
At the same time, the core process remains the same. Good data supports better learning. Training produces a model. Testing shows whether it works. Monitoring helps keep it useful after deployment. The tools may change, but those principles hold up.
Understanding how machine learning works does not require advanced math at the beginning. It starts with a simple idea: let systems learn from examples, then check whether they can make sound decisions on new data. Once that part is clear, the rest of the field becomes much easier to follow.