How Recommendation Algorithms Work in Services
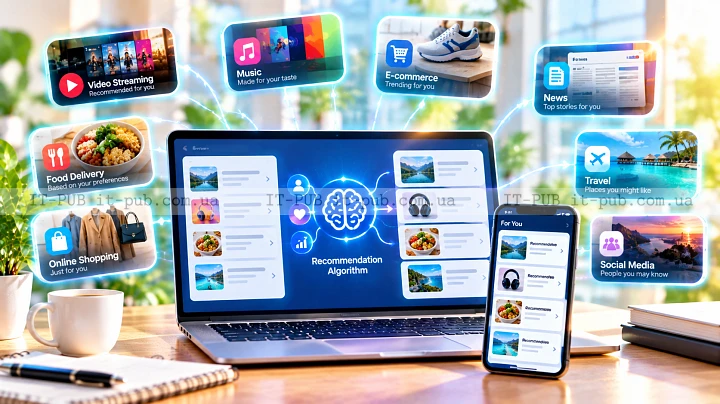
How recommendation algorithms work is one of the key questions behind modern digital services. These systems decide which videos, products, articles, songs, or posts show up first, often in ways that feel surprisingly personal. There is no magic in it. What you get is a mix of data, pattern detection, and ranking logic built to predict what a user may find useful or interesting.
Recommendation systems are now part of almost every major platform, from streaming services and online stores to news apps and social networks. They help people find relevant content faster, and they help services hold attention. If you understand how platforms suggest content, it becomes easier to use them more deliberately and to see both what they do well and where they fall short.
Why recommendation systems exist
The internet has far more content than anyone can sort through manually. Without some kind of guidance, users would have to dig through endless options on their own. Recommendation systems cut through that overload by surfacing items that seem most relevant.
In practice, that can mean a shopping platform showing products similar to what someone viewed earlier. A streaming service might suggest a series that fits past viewing habits. A news app may push topics that line up with a reader’s interests. The point is not just to show what is popular. It is to show what is likely to matter to a specific person.
That focus on relevance is what gives recommendation systems their power. It also explains why two people can open the same service and see completely different results.
The basic idea behind recommendations
At the center of any recommendation engine is a simple question: what is this user likely to want next?
To answer it, the system looks for patterns. It checks what a user clicked, watched, bought, skipped, liked, saved, or ignored. Then it compares those actions with the behavior of many other users. From that, it builds a prediction.
That prediction is never perfect. It is a best estimate based on the signals available at that moment. In many cases, the system does not choose a single item. It builds a list of possible candidates and ranks them by how likely they are to be useful or engaging.
That ranking step is where a lot of the real decision-making happens. A service may know about thousands of possible items, but only a handful can appear at the top of a page or feed. Content recommendation algorithms decide which ones get that space.
The data recommendation systems use
Recommendation systems depend on data, but some signals matter more than others. The most common ones are behavior-based: clicks, watch time, purchase history, search terms, likes, shares, and repeat visits. Negative signals can matter too, including items that were skipped quickly or closed right away.
Some services also use profile data. That can include language, device type, approximate location, or broad interests. Context often matters as well. The same person may want different things in the morning than in the evening, or on a phone instead of a laptop.
The important point is that recommendation systems rarely rely on one signal alone. They piece together lots of small clues. One click may mean very little. A repeated pattern around the same topic means much more.
Collaborative filtering and content-based suggestions
Two classic approaches still shape many recommendation systems.
Collaborative filtering looks at user behavior across a crowd. If two people have acted in similar ways, the system assumes they may like similar things later on. If many users who liked one item also liked another, the platform may recommend that second item to someone with a similar taste profile. This works best when there is enough activity to reveal strong patterns.
Content-based recommendation looks at the item itself. It compares features such as topic, genre, style, author, or category. If someone regularly reads articles about cybersecurity, the system may suggest other articles with similar themes. This approach is useful when item details are clear and user behavior is still limited.
A lot of services combine both methods. That gives them a wider view. Collaborative filtering captures shared behavior, while content-based logic helps keep personalized recommendations relevant even when a user history is still thin.
How machine learning improves recommendations
Machine learning recommendations go further than simple rule matching. Instead of relying only on fixed if-then logic, the system learns from data and adjusts its predictions over time. That lets it catch patterns that would be difficult to define by hand.
A person does not always choose the same kind of content, but their behavior can still reveal stable preferences. They may prefer short-form content in one context and long-form content in another. With enough data, machine learning can detect that.
These models are often used to score possible recommendations. Each item gets a relevance score based on many signals, and the highest-scoring items rise to the top. As the user keeps interacting, the system updates its picture of that user and refines future suggestions.
That is one reason recommendation systems feel so dynamic. They are not static catalogs. They shift with behavior.
Why feedback loops matter
Recommendation systems do not just observe users. They shape user behavior too. That creates a feedback loop.
If a platform shows one kind of content more often, people are more likely to click it simply because it is there and easy to see. Those clicks then reinforce the system’s assumption that the content is relevant. Over time, the algorithm may push similar items even harder.
Sometimes that is useful. It can help people reach content they genuinely care about more quickly. But it can also reduce variety. A single click on one topic can lead the system to overestimate how important that topic really is. That is why recommendation systems sometimes start to feel repetitive.
Good platforms try to balance relevance with diversity. They want the feed to stay useful without locking users into a narrow pattern.
The role of ranking and filtering
A recommendation engine usually works in stages. First it gathers a large pool of possible items. Then it filters out anything clearly irrelevant, unavailable, or already seen. After that, it ranks what remains.
This ranking stage is where many services make their strongest choices. The ranking can be shaped by different goals. A news service may care more about freshness and relevance. A shopping platform may care more about which products are likely to convert. A streaming service may focus on what keeps a user engaged longer.
The same system may also tweak rankings for practical reasons. It might avoid duplicates, balance new items with familiar ones, or limit content that has already been promoted heavily. Users do not always see these decisions directly, but they shape the experience every time a feed loads.
Personalization is useful, but not neutral
Personalized recommendations save time and cut down noise. They help users discover material that might otherwise stay buried. That is the main strength of a recommendation engine.
Still, personalization is not neutral. The system reflects the data it gets and the goals it has been built to optimize. If a service treats clicks or watch time as the main measure of success, it may favor content that grabs attention quickly rather than content that is most accurate or most valuable.
That is why recommendation systems come up so often in discussions about quality, trust, and user well-being. A platform can be technically effective and still produce a narrow or overly aggressive feed. The design choices behind the system matter just as much as the math.
Common limits of recommendation algorithms
Recommendation algorithms are good at pattern matching, but they are not all-knowing.
One familiar problem is the cold start issue. When a new user joins a service, there is very little behavior data to work with. The system may have to lean on general popularity, basic profile details, or broad category choices until it learns more.
The same problem affects new items. A newly published article or product has almost no interaction history, so the system may struggle to rank it properly. Some services deal with this by mixing new items into recommendations or by relying more on content features instead of behavior alone.
Another limit is overfitting to past behavior. A system can assume that old preferences will keep applying forever. Real people do not work that way. Interests change, and needs shift with context. Good recommendation systems try to adapt, but they never get it exactly right every time.
Bias is another issue. If the underlying data is skewed, the output can be skewed too. Popular items may gain even more visibility, while niche but valuable content stays hidden.
How services try to improve recommendation quality
To improve recommendation quality, services usually combine several methods. They may use explicit feedback, such as ratings or follows, alongside implicit feedback like clicks and time spent. They may test different ranking models and compare how each one performs. They may also add diversity rules so the feed does not become too predictable.
Some systems give users more control. They let people mark content as not interesting, save items for later, or adjust topic preferences. Those actions help the algorithm learn faster and reduce unwanted suggestions.
Continuous evaluation matters too. A recommendation system should not be judged only by how many clicks it generates. It should also be measured for relevance, variety, and long-term usefulness. That wider view helps prevent short-term optimization from damaging the experience later.
What users can do to shape recommendations
Users are not passive in this process. Recommendation systems learn from behavior, so even small actions can change what appears next.
If someone wants more of a certain topic, interacting with related content usually helps. If they want fewer similar suggestions, they can skip, hide, or mark content as irrelevant when the platform allows it. On some services, clearing watch history or search history can also reset part of the profile.
It helps to remember that algorithms tend to interpret behavior literally. A click may count as interest even if it came from pure curiosity. A long pause on a page may be read as engagement too. Keeping that in mind makes it easier to manage the feed more intentionally.
Why recommendation systems matter for IT and digital products
For product teams, recommendation algorithms are not just a feature. They are part of the architecture of the user experience. They shape discovery, retention, and sometimes trust. A weak recommendation system can make a service feel cluttered or off-target. A strong one can make a huge platform feel simple and personal.
For IT practitioners, the main takeaway is that recommendation systems sit at the intersection of data engineering, model design, product goals, and user behavior. The technical side matters, obviously. So does the human side. A useful system has to respect context, adapt to change, and avoid reducing people to a single pattern.
That is why understanding how recommendation algorithms work matters beyond any one platform or industry. The same logic appears in entertainment, e-commerce, publishing, education, and enterprise software. Anywhere there is too much content to sort manually, recommendation systems step in.
A practical way to think about recommendations
The simplest way to think about recommendation systems is to treat them as assistants, not judges. They do not know what is truly best. They estimate what is likely to be relevant based on patterns in data.
That makes them useful, but not final. A recommendation can point someone in a direction, but the user still decides what matters. Once people understand that balance, they can use digital products with more awareness and usually with better results.
Recommendation algorithms will keep changing, but their purpose stays familiar. They help people find things faster in a world full of options. When they are designed well, they make that search feel less overwhelming and more personal.