Meta removes clause that sparked AI scraping fears
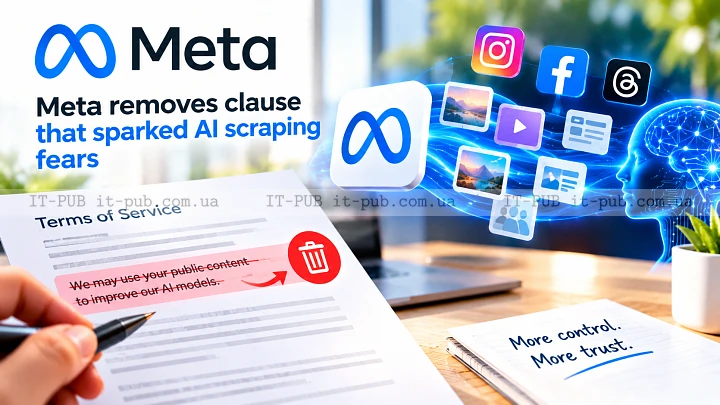
Meta deleted a business-terms clause after concerns it could cover website content use for AI training, while saying its web crawling practices did not change.
Meta has removed a clause from its commercial terms of use after it drew scrutiny over what it seemed to permit. The language suggested Meta could use content from business accounts’ domains, web pages, or URLs to “provide, develop, improve, research, train, and maintain the integrity of” its products and services. That quickly raised concerns that the company was claiming room to scrape publisher websites for AI-related purposes.
Meta says the change does not reflect any shift in how it crawls the web. Still, the wording was broad enough to alarm legal experts and attract attention well beyond routine terms updates. In the current debate over AI training data, even a single sentence can carry real weight.
The clause that triggered the backlash
The controversy centered on one sentence in Meta’s updated business terms. Read plainly, it appeared to give the company permission to use content tied to a business account’s online properties for a wide range of purposes, including training.
That is what made the clause stand out. Legal experts interviewed by Nieman Lab said it could be interpreted as allowing Meta to collect and use website content from publishers with Meta business accounts. As IT-PUB News notes, that reading landed in an already tense environment, where AI companies face growing scrutiny over how they gather training data.
The concern was not merely abstract. Meta defeated a high-profile copyright lawsuit last year, but other cases against AI companies — including Meta — are still ongoing. In that context, broad language in commercial terms can quickly become a flashpoint.
Meta says the language was meant for ads and business tools
Meta disputed the broader interpretation of the clause and said the updated terms did not signal any change in how it crawls the web.
Now, The Verge reports that the provision has been removed entirely. In a statement, Meta said: “We’ve heard you and want to clarify: the crawling terms we consolidated only applied to our ads and business products, and we’ve clarified that in the terms themselves,” adding that it “does not change how Meta uses web crawlers.”
That matters because it narrows the apparent scope of the original wording. Rather than suggesting broad use of business-account content across Meta’s products, the company now says the terms were intended to cover only its ads and business products.
Why the wording mattered to publishers and businesses
The issue drew attention because it touched a particularly sensitive question in the AI era: who gets to use online content, and for what. For publishers and other businesses that maintain a presence on Meta’s platforms, the wording of platform terms can shape how their material is understood and handled behind the scenes.
If those terms appear to permit broad reuse of web content, businesses may worry about scraping, training data, and control over what they publish. Even without a confirmed change in practice, language like this can signal risk to companies that depend on online content for traffic, branding, or direct communication with audiences.
For Meta, the episode also shows how quickly commercial terms can become part of the wider argument over AI development. A company may treat such wording as legal or operational cleanup. Outside observers may read it instead through the lens of data use and model training.
A terms change that reflects bigger AI tensions
Removing the clause does not settle the larger dispute over AI training and web content. It does, however, show how closely the fine print is now being watched. Terms of service that might once have passed with little notice can now trigger immediate concern from lawyers, publishers, and users tracking how tech companies describe their rights over online material.
Meta’s statement suggests it was trying to clear up confusion, not announce a new policy. Even so, the episode underscores how sensitive web crawling and AI training have become — and how a single line in business terms can raise broader questions about where a platform believes its rights begin and end.